
Sample confusion matrix: retain the provenance before reusing metrics
filename literally says SAMPLE confusion matrix, keep that attached
fractional counts + June file vs September split sheets. not automatically the same experiment
The document is explicitly named “JIC - sample confusion matrix.” Its two normalized rows are unbal: 0.9744, 0.0256 and bal: 0.0528, 0.9472; it also contains fractional weighted values 17,539.2, 460.8, 1,900.8 and 34,099.2. Fractional entries are a reason to preserve this as a sample/derived table rather than assert they are raw counts of classified examples.
The sheet reports F1 = 0.9369230769, sensitivity = 0.9744 and overall accuracy = 0.9613259669. The poster separately quotes accuracy 0.9608. Before copying one into a benchmark table, confirm row/column orientation, the positive class, weighting and the run that generated it. For integer predictions, compute F1 = 2TP/(2TP+FP+FN) and accuracy = (TP+TN)/(TP+TN+FP+FN) from the saved predictions.
This file was created/modified in June 2023, whereas the recovered training/test sheets are September snapshots. Do not join them into one experiment merely because both involve the GRU. Missing reference items: raw predictions, threshold, number of windows, class supports and exact checkpoint.
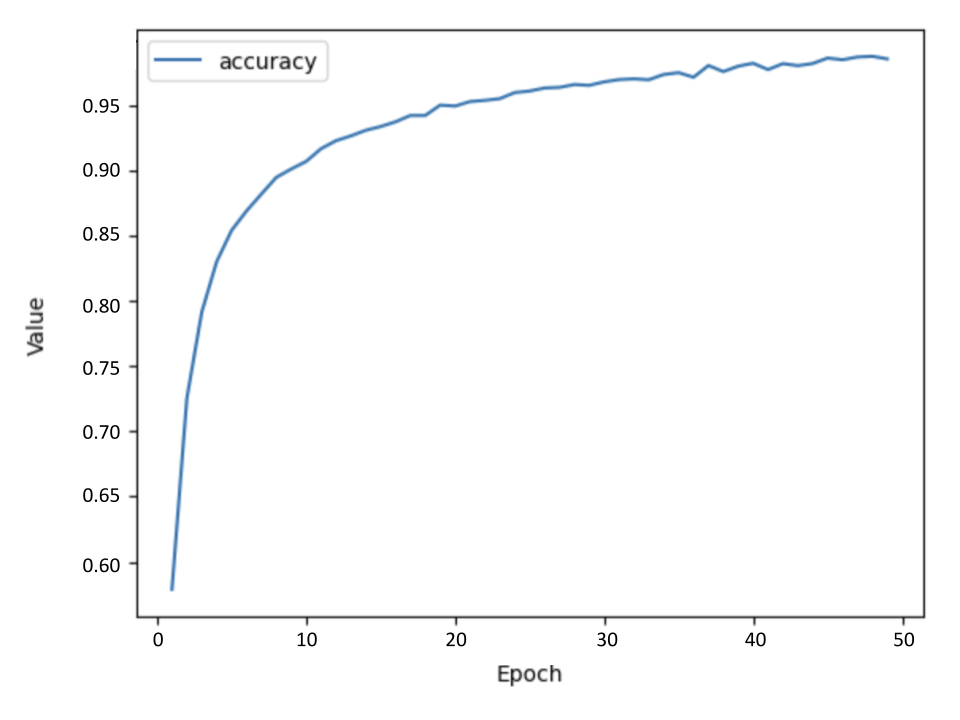
GRU accuracy curve from the JIC poster.